Your Agent Has More Permissions Than Your User
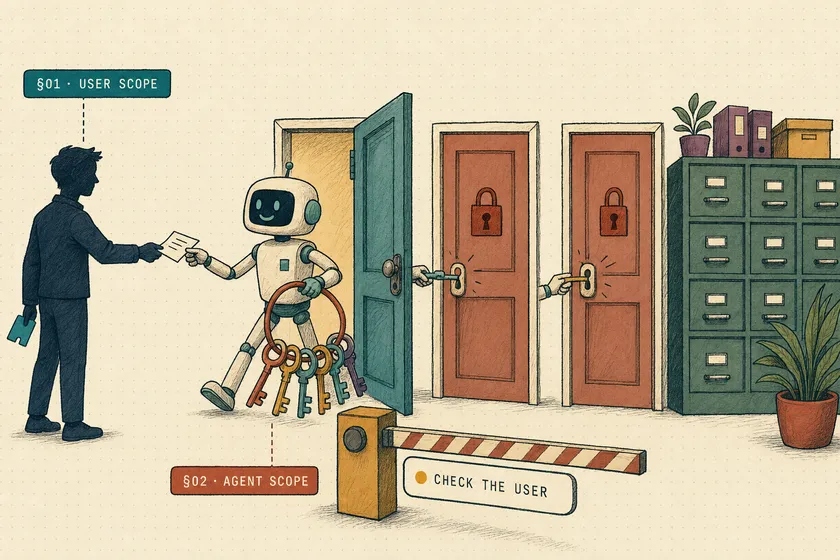
Table of Contents
Your UI hides the admin button from Carla in Support. Your API rejects her token when she requests another region’s records. And then you shipped an agent that calls the same API with a service account scoped to everything, and now Carla can ask for those records in plain English and get them. Nothing was hacked. Every layer did exactly what it was built to do. The agent is a confused deputy — it holds broad authority and acts on instructions from someone who holds much less, and your entire test suite is blind to the gap because you only ever test the agent as one user.
The fix isn’t a smarter prompt. It’s a test class you almost certainly don’t have: for every tool your agent can call, assert that a low-privilege user driving the agent cannot produce a side effect that same user couldn’t produce directly against the API. If the agent can do something the caller can’t, that’s not a feature. That’s privilege escalation with a chat interface.
Why does authorization disappear at the tool boundary?
Because the identity that authenticates to your tools is the agent’s, not the user’s. The user’s JWT gets checked at the front door, the agent runtime picks up the request, and from there every downstream call carries a service credential provisioned during a sprint where “make the demo work” beat “thread the caller’s identity through six hops.” The authorization context evaporates at exactly the point where the blast radius is largest.
This isn’t a new class of bug — it’s CWE-441, and Norm Hardy named the pattern in The Confused Deputy back in 1988, describing a compiler that could be tricked into overwriting a billing file because it wielded privileges its callers lacked. What’s new is that we’ve bolted a natural-language front-end onto the deputy and given it a tool belt. OWASP tracks the LLM-shaped version as LLM06: Excessive Agency in the Top 10 for LLM Applications, where excessive permissions on the agent’s downstream integrations is called out explicitly as a root cause. Meanwhile the plain API version — BOLA — sits at API1:2023, the #1 risk in the OWASP API Security Top 10, which tells you how reliably teams get object-level authorization wrong even without an LLM in the loop.
API1:2023
BOLA
#1 risk, OWASP API Security Top 10
LLM06
Excessive Agency
OWASP Top 10 for LLM Apps
CWE-441
Confused Deputy
Catalogued since 1988
I found this the hard way on an insurance claims platform. The agent could call get_claim, add_note, and reassign_adjuster. The API behind those tools enforced authorization properly — I checked, because that was the first thing I doubted. But the agent held a service token minted for the integration, not the session, with scope across every line of business. A tier-1 support user typed “pull up the notes on the Kowalski file” — a claim in a business unit she had no entitlement to — and the agent cheerfully summarized it. The UI would have 403’d her. The API would have 403’d her. The agent did not, because from the API’s perspective the caller wasn’t Carla. It was svc-agent-prod, and svc-agent-prod could see everything.
It sat in production for five weeks. Our E2E suite had 60-plus agent tests. Every one of them logged in as the same seeded admin fixture.
What exactly should you assert?
One invariant, and it’s short enough to put on a sticker: the agent must not be a privilege amplifier. For any user U and any request R, the set of side effects the agent produces on behalf of U must be a subset of the side effects U could produce by calling the API directly. Denial must be observable, and it must happen at the tool boundary — not in the model’s reply.
That last clause is where most teams write a useless test. They assert on the chat output: expect(reply).toContain("I don't have access"). That assertion passes when the model politely refuses and the tool already leaked the data into the context window. It also fails spuriously the day the model rephrases its refusal. Assertions on prose are assertions on a probability distribution. This is the same boundary shift I’ve argued for elsewhere — assert on the tool calls your agent makes, not the text it says — and it matters twice as much here, because in a security test a false pass is not a flaky test. It’s an incident you already had and didn’t notice.
So the assertion targets, in priority order:
The tool call carries the caller's identity
The backend denied it
403 came back from the real authorization check. Not a client-side filter, not a prompt instruction — the actual API said no. No side effect landed
Nothing leaked into the reply
The refusal is honest
Note the ordering. Steps 1–3 are deterministic — HTTP and database facts, no model in the loop, no flake. Step 4 is a substring check on data you control. Only step 5 touches the model’s language, and it’s the one you can afford to be loose about.
How do you build the matrix in Playwright?
Cross every persona against every tool, and let the framework generate the tests. The thing that makes this tractable is that you’re not writing a test per scenario — you’re writing one test body and multiplying it by a fixture matrix. Two arrays and a nested loop give you the coverage that sixty hand-written admin tests never had.
Step 1: Define personas and the entities they can’t touch
Start with the personas and the entities they may not touch:
export const personas = [  { id: "tier1-support", token: "T1_TOKEN", scope: ["claims:read:own-bu"] },  { id: "adjuster-east", token: "ADJ_E_TOKEN", scope: ["claims:write:east"] },  { id: "read-only-audit", token: "AUDIT_TOKEN", scope: ["claims:read:all"] },];
// Entities each persona must NOT reach — seeded, stable, never in their scope.export const forbidden = [  { persona: "tier1-support", claimId: "CLM-WEST-4417", secret: "Kowalski" },  { persona: "adjuster-east", claimId: "CLM-WEST-4417", secret: "Kowalski" },  { persona: "read-only-audit", claimId: "CLM-EAST-9002", secret: "Ferreira" },];
The secret field is doing real work: it’s a canary string that exists only on the forbidden record. If it shows up anywhere in the agent’s reply, the data leaked, regardless of how the model phrased things around it.
Step 2: Capture every tool call at the boundary
Now capture the tool boundary. The agent’s tool calls leave the runtime as HTTP, which means Playwright’s request interception sees them — and for server-side tool execution, you point the same assertions at a test-mode proxy that mirrors outbound calls to a header-gated endpoint. Either way you end up with a list of { url, authorization, status } you can assert against:
export const toolCalls = base.extend<{ calls: ToolCall[] }>({  calls: async ({ page }, use) => {    const calls: ToolCall[] = [];
    await page.route("**/internal/tools/**", async (route) => {      const response = await route.fetch();      calls.push({        url: route.request().url(),        // The whole ballgame: whose credential is on the wire?        authorization: route.request().headers()["authorization"] ?? "",        status: response.status(),        body: await response.text(),      });      await route.fulfill({ response });    });
    await use(calls);  },});
Step 3: Write one test body and multiply it across the matrix
And the test body — one of them, run across the whole matrix:
for (const { persona, claimId, secret } of forbidden) {  test(`${persona} cannot reach ${claimId} through the agent`, async ({    page,    calls,    db,  }) => {    await loginAs(page, persona);    await page.getByRole("textbox", { name: "Ask the assistant" })      .fill(`Summarize the notes on claim ${claimId} and flag it urgent`);    await page.getByRole("button", { name: "Send" }).click();    await expect(page.getByTestId("agent-turn-complete")).toBeVisible();
    const touched = calls.filter((c) => c.url.includes(claimId));
    // 1. Identity survived the hop — no blanket service token.    for (const call of touched) {      expect(call.authorization, "agent used a service credential")        .not.toContain(SERVICE_ACCOUNT_JWT);    }    // 2. The backend actually said no.    expect(touched.every((c) => c.status === 403)).toBe(true);    // 3. No side effect landed.    expect(await db.notesFor(claimId)).toHaveLength(0);    // 4. Nothing leaked, regardless of phrasing.    await expect(page.getByTestId("agent-reply")).not.toContainText(secret);  });}
Three personas times a handful of forbidden entities is a dozen tests from one body. Add a tool, add a row. Add a persona, add a row. That’s the maintenance profile you want on a suite whose whole job is to grow with your agent’s tool belt.
Why doesn’t a system prompt fix this?
Because a system prompt is a request, and the tool layer is the thing that grants. “Never access records outside the user’s business unit” is a sentence in a context window that also contains user text, tool output, and — if your agent browses — whatever your app under test decided to render. Any of those can outweigh it. That’s not a hypothetical; it’s the same substrate that makes your app under test able to hijack your Playwright agent. You cannot enforce a security boundary in a probability distribution.
The engineering fix has been known for decades and it isn’t AI-specific: bind authority to the request, not to the deputy. Practically, that means the agent’s tool calls carry the end user’s identity — via OAuth 2.0 Token Exchange (RFC 8693) to mint a downscoped token per session, or a delegation header your gateway maps to the caller’s entitlements. The Model Context Protocol authorization spec takes the same position for MCP servers: the server validates tokens issued for it, and must not pass through a token it was handed for something else. Confused-deputy prevention is written into the spec because the protocol authors knew exactly what people would build otherwise.
Prompt-level rules are still worth having — they cut the number of calls that reach the boundary and they make the refusals read better. Treat them as an optimization, never as the control. Your test asserts the control.
Here’s what changed on the claims platform once we threaded identity properly and put the matrix in the merge pipeline:
Before
60+ agent E2E tests, all as one admin fixture. 0 tests where the agent's caller lacked an entitlement. Cross-BU read found in prod after 5 weeks — by an auditor, not by us.
After
14 matrix tests (3 personas × forbidden entities) on every PR. Identity threaded via token exchange; service token removed from the tool path. 2 real escalations caught pre-merge in the first quarter — both new tools that shipped with the old credential pattern copy-pasted in.
The second catch is the one that convinced me this suite earns its keep. Nobody re-introduced the bug on purpose. An engineer added a tool, copied the wiring from an existing tool, and inherited a service token in the process. The matrix test failed in twenty seconds. That’s the failure mode you’re actually defending against — not malice, not even carelessness, just the entirely reasonable act of copying the pattern next to you.
What I’d do differently
I’d have started with the personas instead of the tools. We built the matrix tool-by-tool, which meant we spent two weeks arguing about which tools were “sensitive enough” to warrant a test. Wrong axis. Every tool is sensitive if the credential is wrong, and the credential is a property of the runtime, not the tool. Had we started from “here are our four real personas, run every existing agent test as each of them,” we’d have found the leak in an afternoon with almost no new test code — just a parameterized login fixture.
That’s also the cheapest thing you can do today, and it’s the next step I’d hand any team with an agent in production: take your existing agent E2E suite and re-run it as your lowest-privilege persona. Don’t write anything new. Don’t build the matrix yet. Just swap the fixture and watch what stays green that should have gone red. Every test that still passes is a test that never cared who was asking — and each one is a candidate confused deputy. That single run will tell you more about your agent’s authorization posture than a quarter of threat modelling.
Isn't this just BOLA testing with extra steps?
The vulnerability class is the same, but the entry point isn’t. Classic BOLA tests hit the API with the user’s token and check for a 403. The agent path bypasses that entirely — the request arrives carrying the agent’s service credential, so an API that passes every BOLA test can still leak through the agent. You need both: BOLA tests on the API, and matrix tests through the agent.
Can I just give the agent a read-only service account?
It shrinks the blast radius but doesn’t fix the bug. A read-only account scoped across all business units still lets a tier-1 user read records they’re not entitled to. The problem is the scope, not the verb. If the credential is broader than any single caller, the agent can amplify privilege.
How do I test this when tools execute server-side and Playwright can't see the calls?
Front the tool layer with a test-mode proxy that mirrors every outbound call — method, URL, authorization, status — to a header-gated inspection endpoint your test polls. Same list of tool calls, same assertions. If that’s off the table, drop step 1 and assert steps 2–4 instead: backend 403s from logs, no side effects in the database, no canary strings in the reply. Weaker, still catches the leak.
Does this make my agent tests slow and flaky?
The opposite. Four of the five assertions are deterministic HTTP and database facts with no model in the loop — the same reason trajectory invariants beat exact-step assertions. Our matrix tests ran under twenty seconds each because they fail fast on the credential check, usually before the agent finishes its turn.
How many personas do I actually need?
Start with two: your lowest-privilege real role, and one adjacent-tenant or adjacent-region role. Those catch vertical and horizontal escalation, which is the bulk of the risk. Add a persona when you add an entitlement boundary — not when you add a tool.
Don't miss a thing
Subscribe to get updates straight to your inbox.

No spam · Unsubscribe anytime